How we built FreeLLMAPI.
FreeLLMAPI turns the scattered free tiers of the LLM ecosystem into one self-hosted, OpenAI-compatible API—then routes every request to the best model and key that still has room. The product itself lives at freellmapi.co; this is the case study of how we built it.
What is FreeLLMAPI?
FreeLLMAPI is a self-hosted router that puts 605 free large-language models from 34 providers behind a single OpenAI-compatible /v1 address — roughly 7.4 billion free tokens a month reachable through one integration instead of 34.
A routing layer scores every model on capability, speed, reliability and remaining quota before a request goes out, tracking RPM, RPD, TPM and TPD per model and per key. When a provider rate-limits, times out or fails, FreeLLMAPI cools that key down and moves the same request to the next viable route, and the calling application never learns a second integration. Provider keys stay in the user’s own SQLite database, encrypted with AES-256-GCM, because FreeLLMAPI runs on the user’s own machine rather than as a hosted middleman. One compatibility layer covers chat, responses, embeddings, images, audio, tools, structured output and MCP, so a single integration reaches all 34 providers.
Updated
The challenge
Free inference was everywhere. Usability wasn’t.
The major AI labs all offer free capacity. Separately, each allowance is small and comes with its own SDK, model names, quota rules and failure modes. Together, they are a serious amount of compute—if something can keep track of all the moving pieces.
FreeLLMAPI makes that fragmentation disappear behind the interface developers already know. An existing OpenAI client only changes two values: its base URL and API key.
const client = new OpenAI({
  baseURL: 'http://localhost:3001/v1',
  apiKey: 'freellmapi-…'
})

await client.chat.completions.create({
  model: 'auto',
  messages
})
The solution
One request in. The best available model out.
A routing layer scores models against capability, speed, reliability and remaining quota. When a provider rate-limits, times out or fails, the key cools down and the same request moves to the next viable route—without the calling app learning a new integration.
Smart routing
Priority, balanced, smartest, fastest, reliable or a custom weighting.
Quota-aware fallover
Tracks RPM, RPD, TPM and TPD per model and key before a request is sent.
One compatibility layer
Chat, responses, embeddings, images, audio, tools, structured output and MCP.
Local-first by design
Provider keys stay in the user’s own SQLite database, encrypted with AES-256-GCM.
Infrastructure you can actually see.
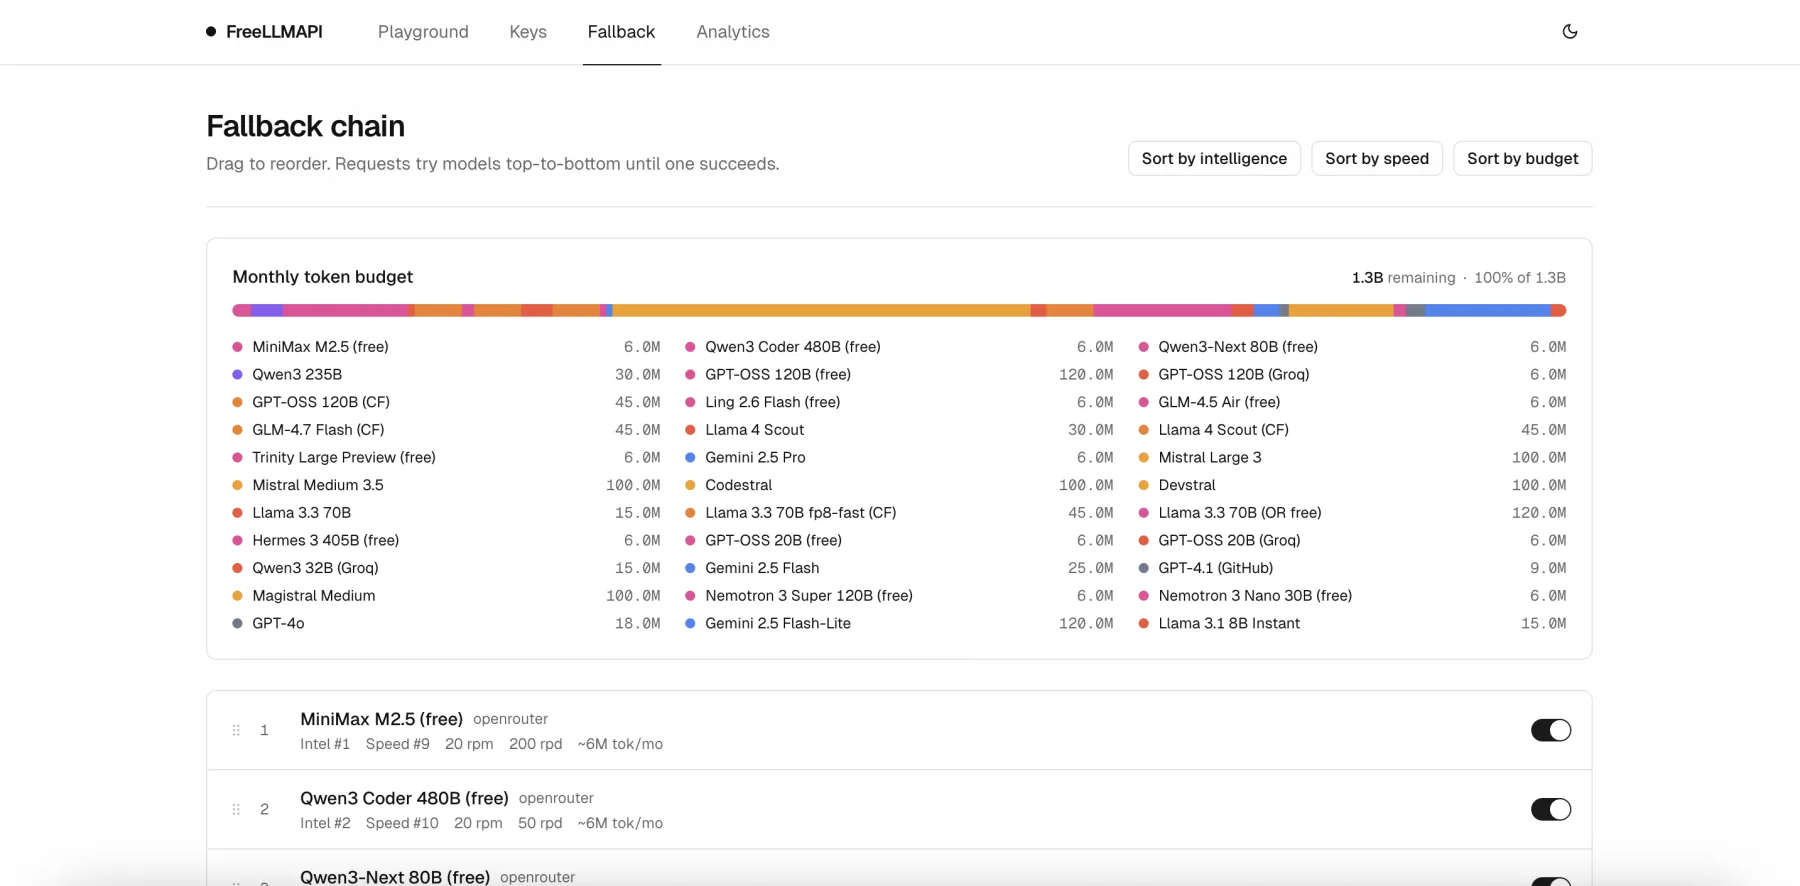
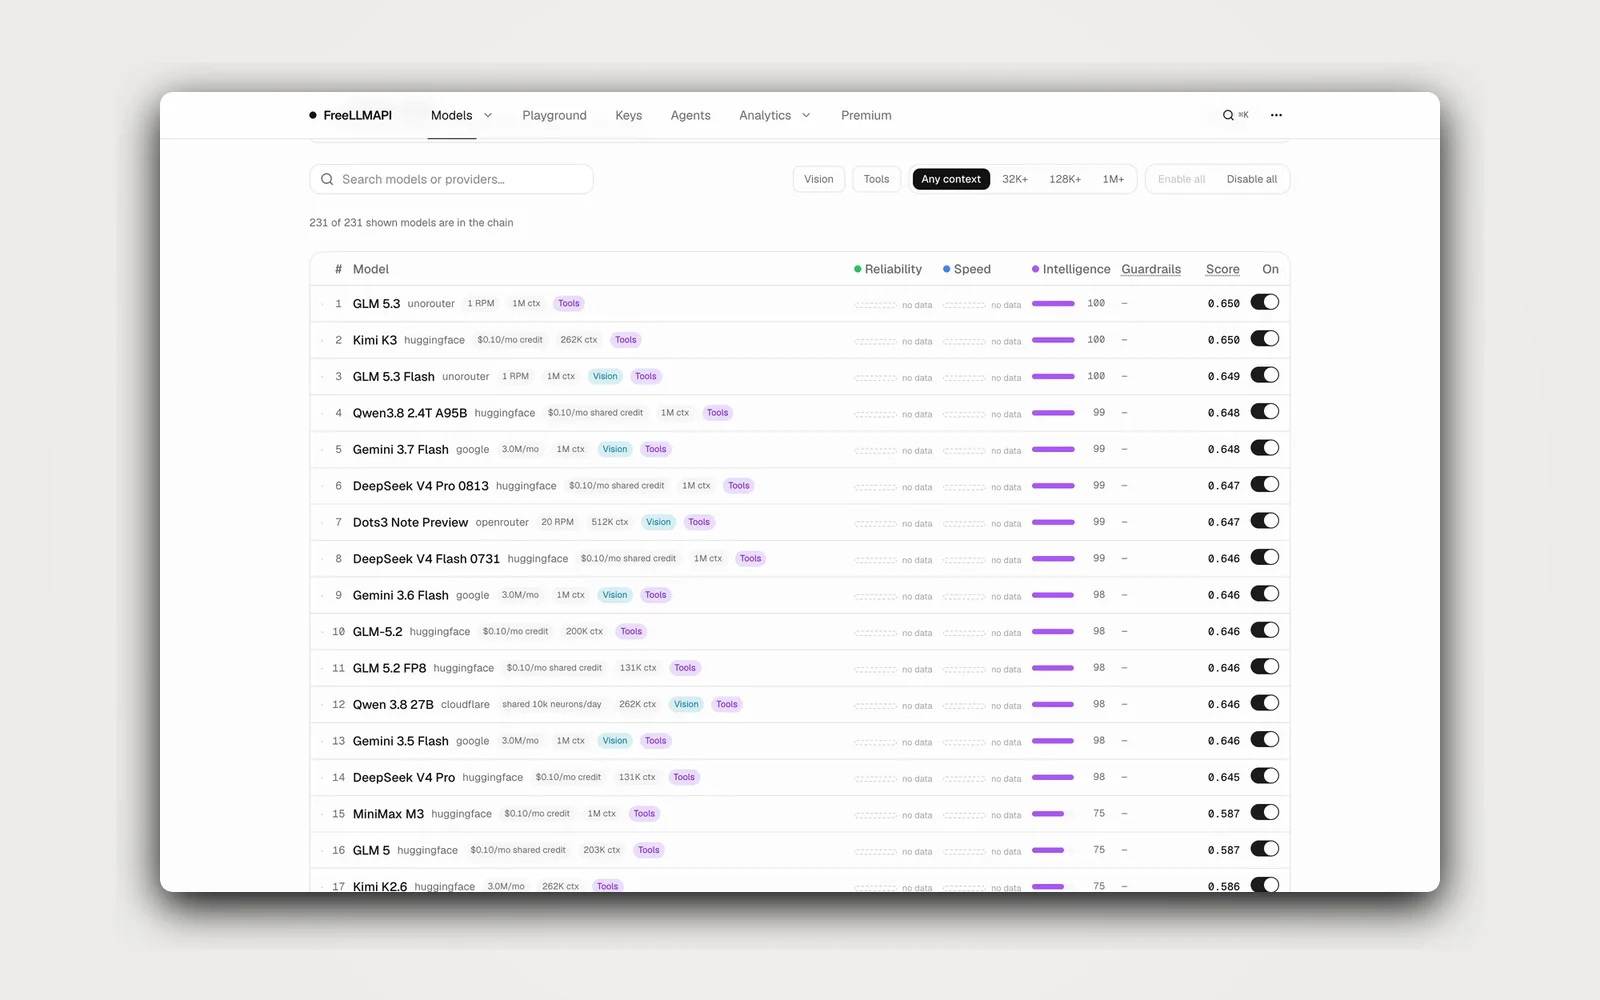
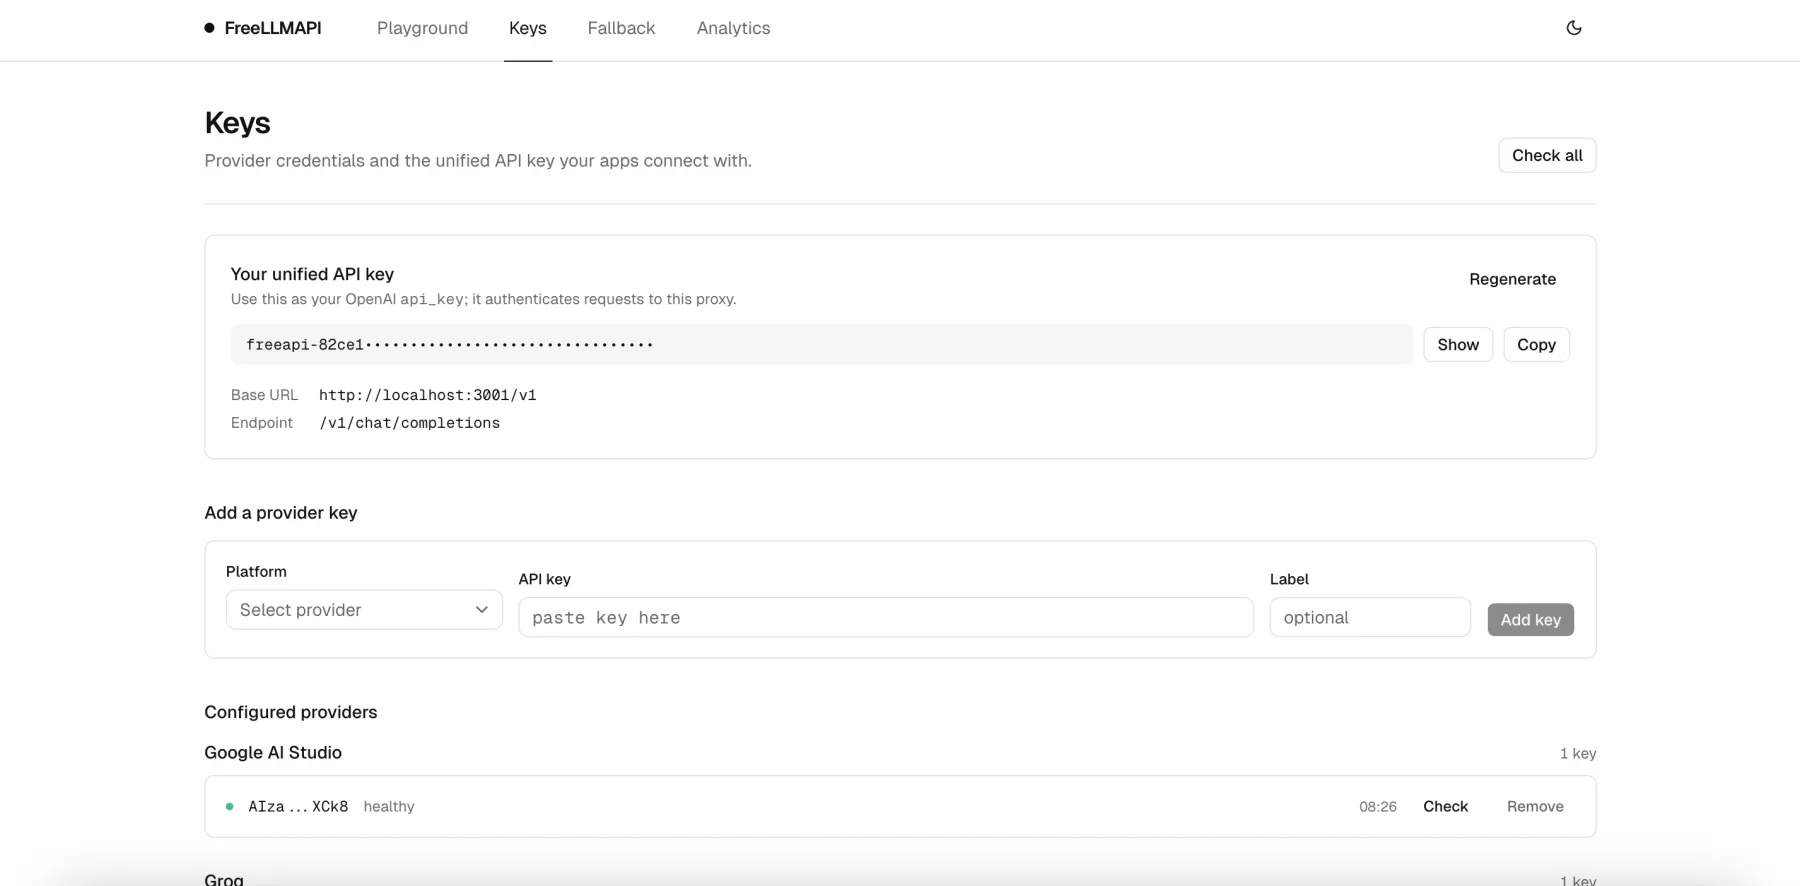
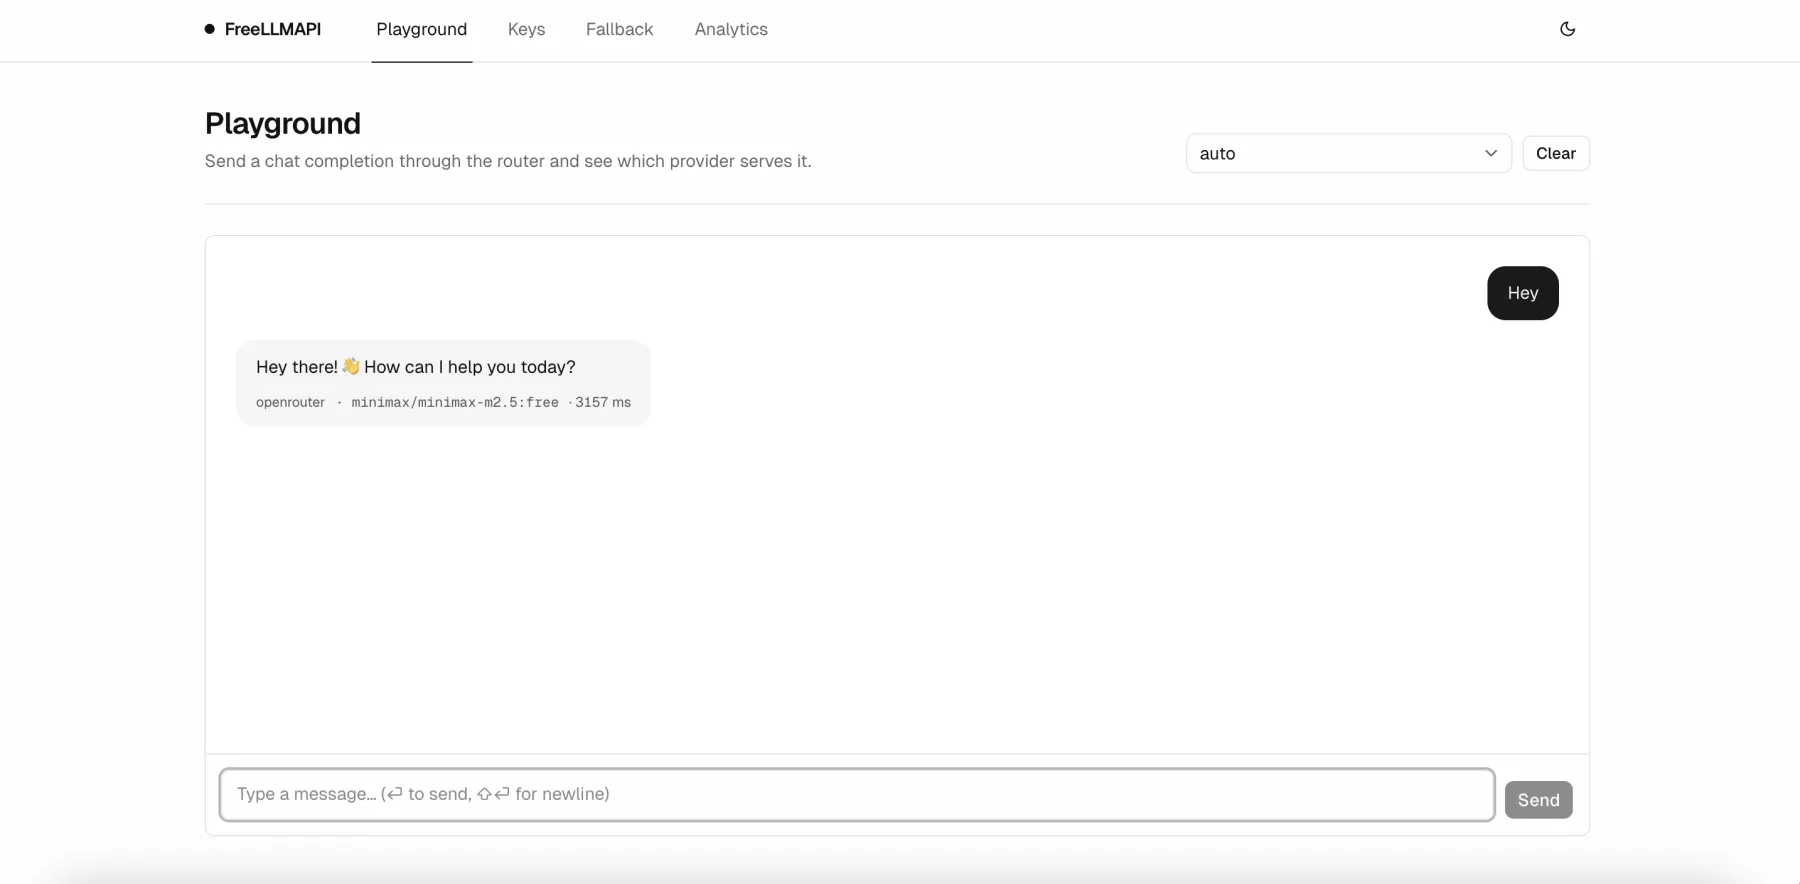
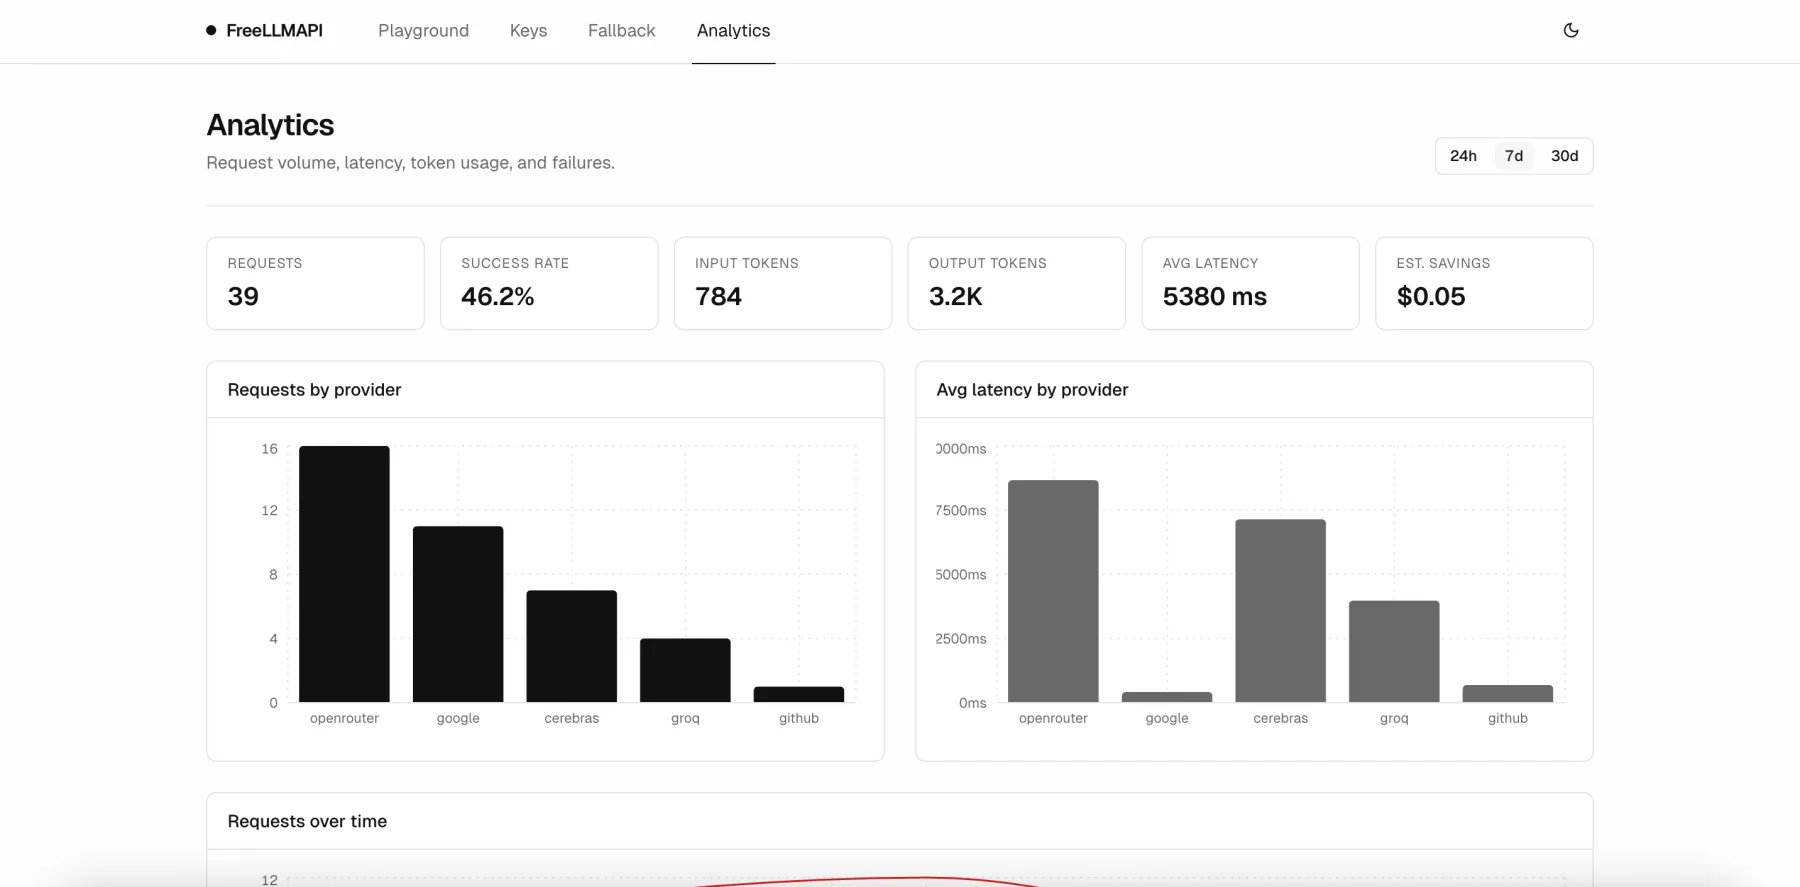
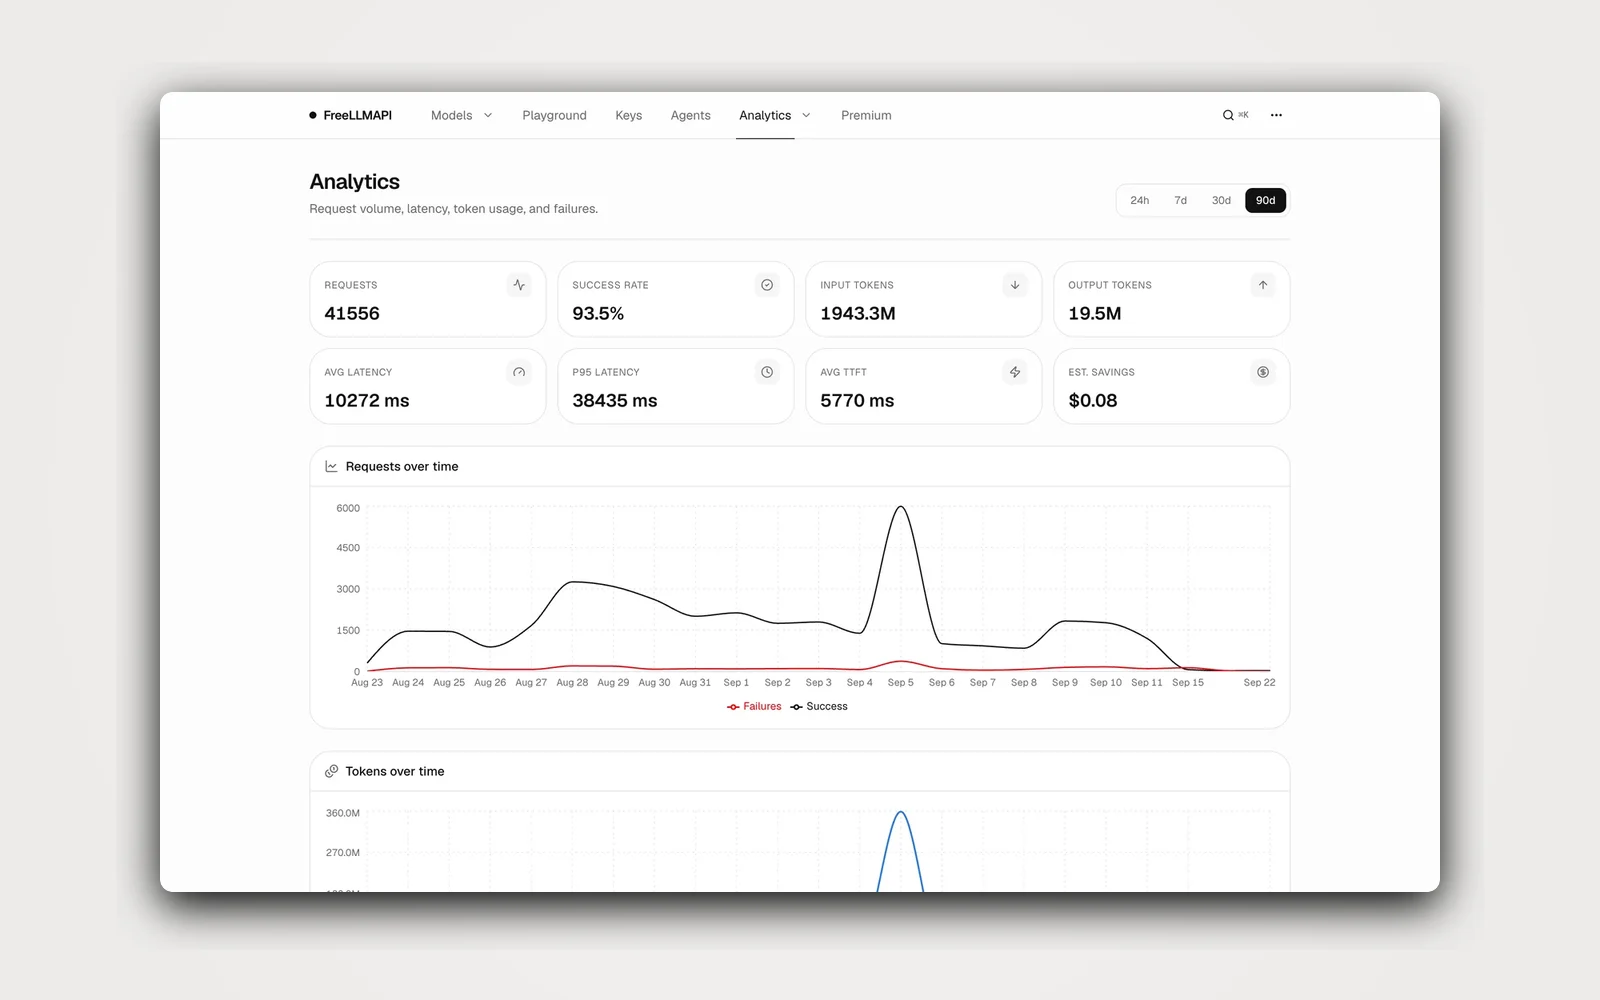
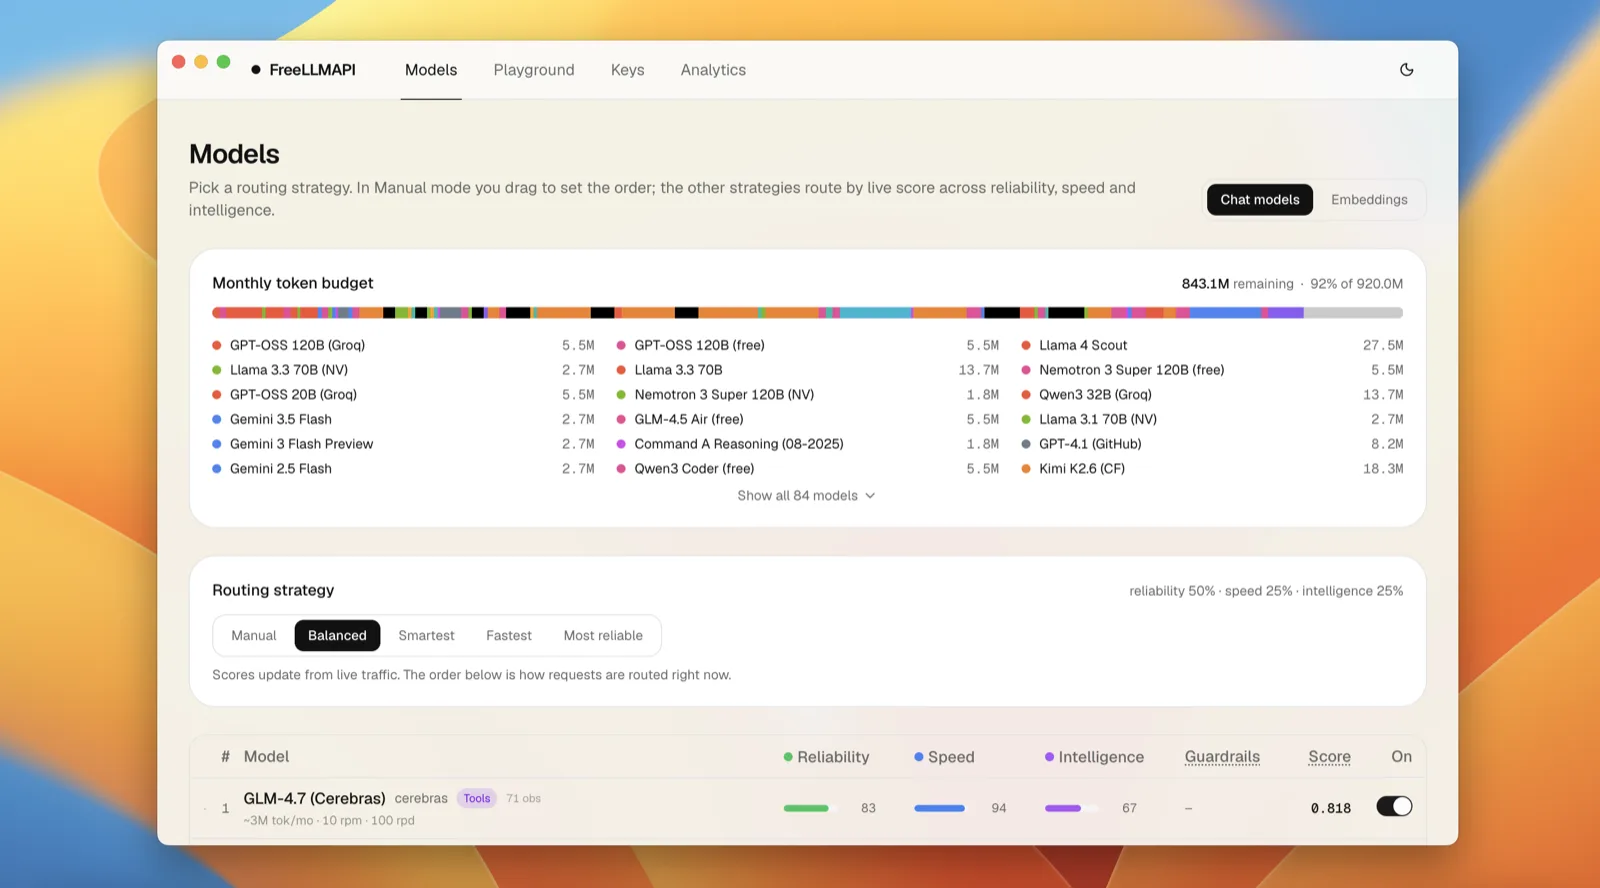
The dashboard makes the router legible. Add and health-check provider keys, inspect the budget across the whole pool, drag the fallback order, test a prompt, then trace request volume and latency back to the provider that served it.
It runs as a Docker service or a native desktop app on macOS and Windows. The UI ships in six languages, while a signed live catalog keeps model launches, quota changes and provider quirks current without a reinstall.
The internet found it.
A few of the posts that sent developers looking for one endpoint across the free-model ecosystem, gathered into one wall.
View post on X ↗0xMarioNawfal@RoundtableSpace · 26 Jun 2026
FREELLMAPI CLAIMS 800M FREE TOKENS A MONTH ACROSS MAJOR LLMS
View post on X ↗Zane Chen@chenzeling4 · 10 Jul 2026
12 API keys just to test different LLMs. FreeLLMAPI puts 18 free providers behind one endpoint. Google, Groq, Cerebras, NVIDIA, Mistral, the list goes on. Router picks the best available model, fails over when one gets rate limited, tracks your token usage per key. 161 free…
View post on X ↗Axel Bitblaze 🪓@Axel_bitblaze69 · 27 Jun 2026
1.7 billion free tokens per month. A month ago i showed you how to route claude code through free providers. someone just shipped the cleanest version of this setup yet… it's called Freellmapi 13,400+ stars on github, MIT licensed, takes 2 minutes to install. what it does:…
View post on X ↗Nicolas Krassas@Dinosn · 25 May 2026
tashfeenahmed/freellmapi: OpenAI-compatible proxy that aggregates free-tier keys from ~14 AI providers with automatic failover. For personal experimentation only. github.com/tashfeenahmed/…
View post on X ↗Alvaro Cintas@dr_cintas · 22 May 2026
"I'm out of free API credits" is officially over 🤯 FreeLLMAPI is an open-source proxy. Each provider's free tier is a toy on its own. Stacked together they add up to ~800M tokens a month. → Google, Groq, Cerebras, NVIDIA, Mistral + 9 more → Drop-in OpenAI endpoint, just swap…
View post on X ↗Shreyas Pandey@Shreyas_Pandeyy · 20 May 2026
Someone created an Open Souce Project where you get 800M free tokens a month, every major LLM this guy literally made you forget about any limits repo: github.com/tashfeenahmed/… good luck in shipping.
View post on X ↗Lavanya Jain (lav)@ilavanyajain · 20 May 2026
800 million tokens from every major LLM, for free completely open source available to all repo: github.com/tashfeenahmed/… if you're still finding excuses to start from today, don't. good luck.
View post on X ↗Enzotoetje@enzotoetje · 20 May 2026
Yo @tashfene made some insane tech!! He built FreeLLMAPI, an open-source API that gives developers access to multiple AI models through one simple interface. No complicated setups, no provider lock-in, just plug in and build. This is honestly game-changing for students, indie…
Catalog figures shown are a point-in-time snapshot from freellmapi.co in September 2026; the live catalog continues to change.
[Demo] — FreeLLMAPI
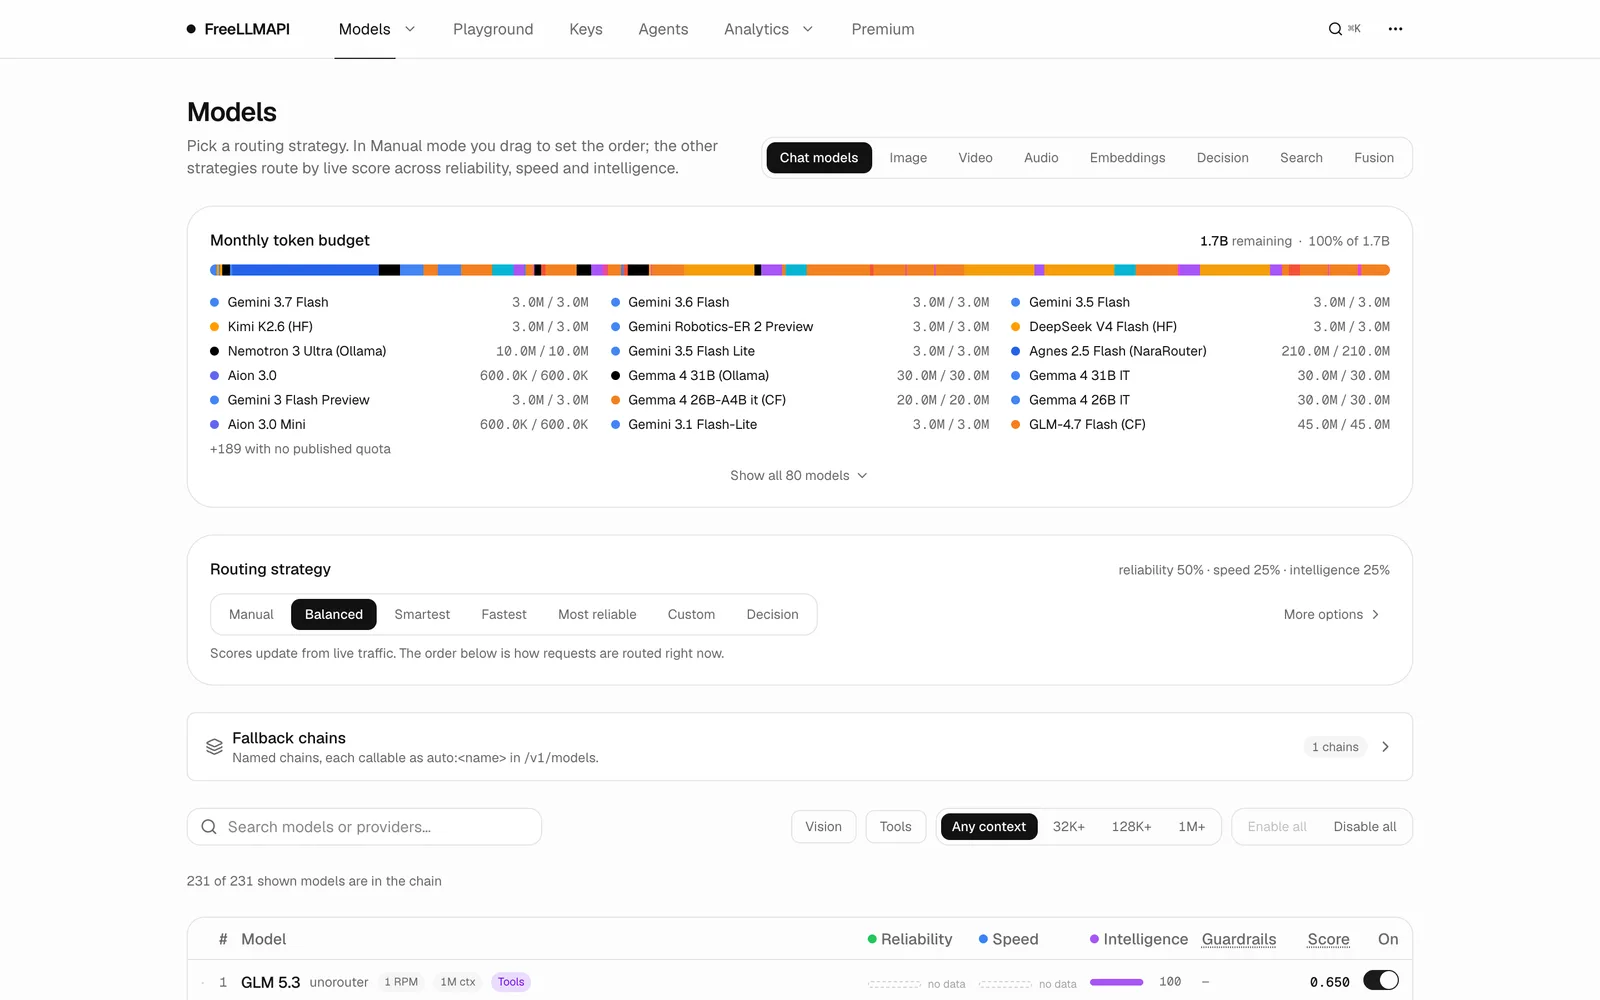
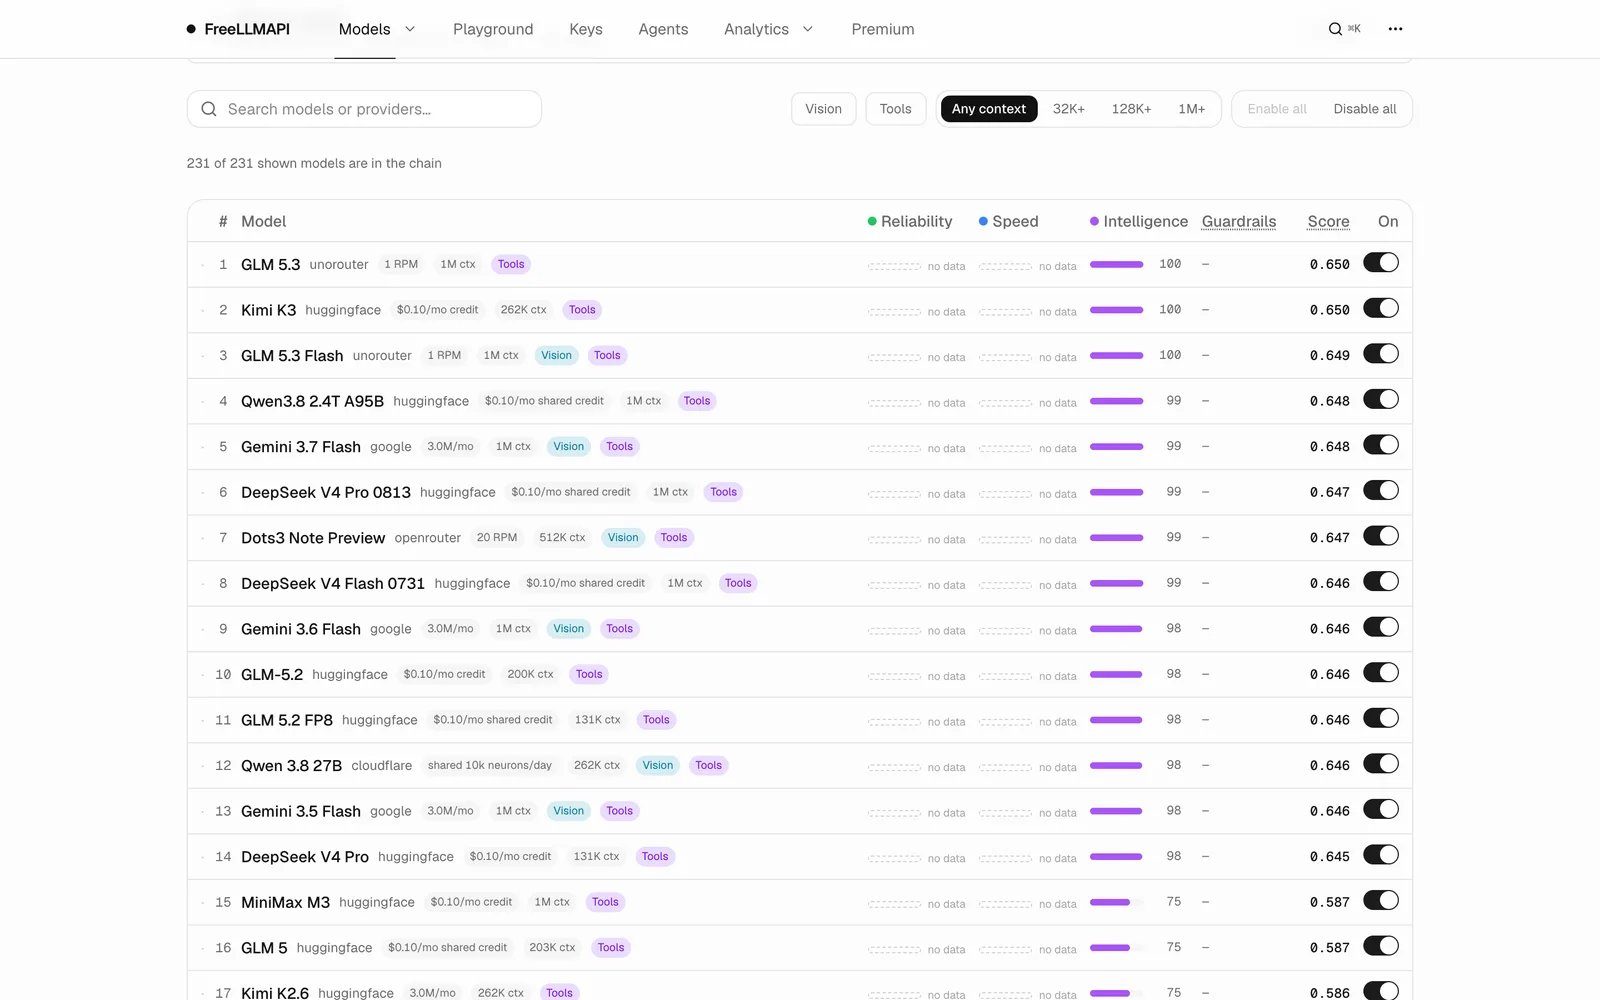
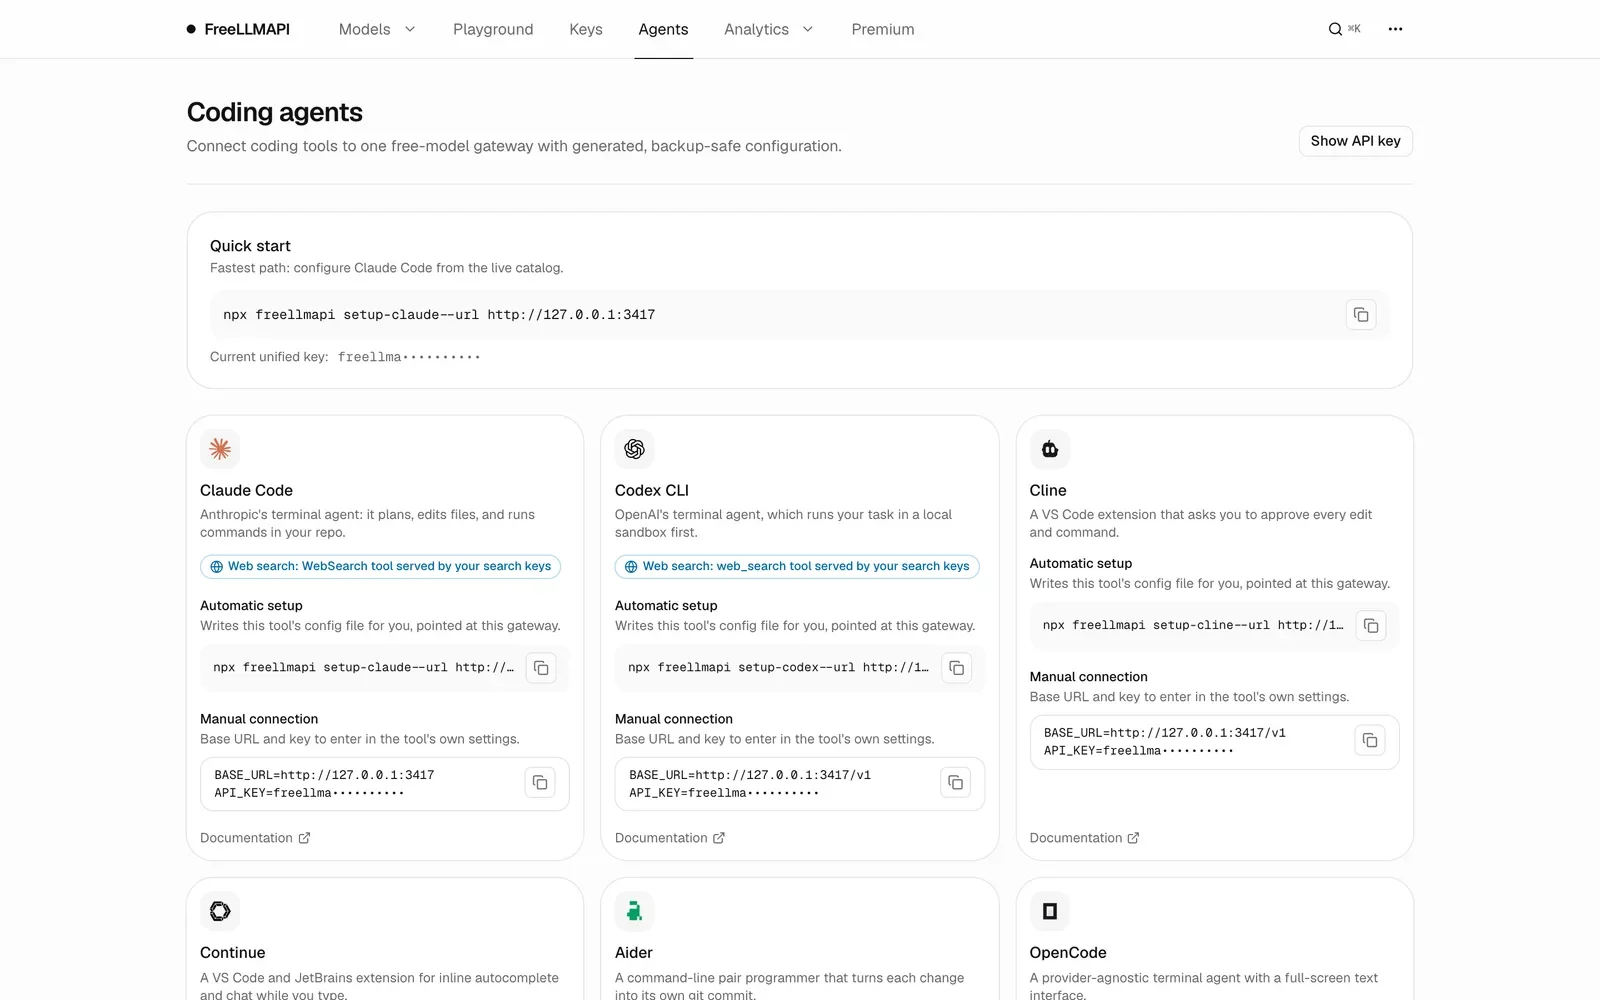
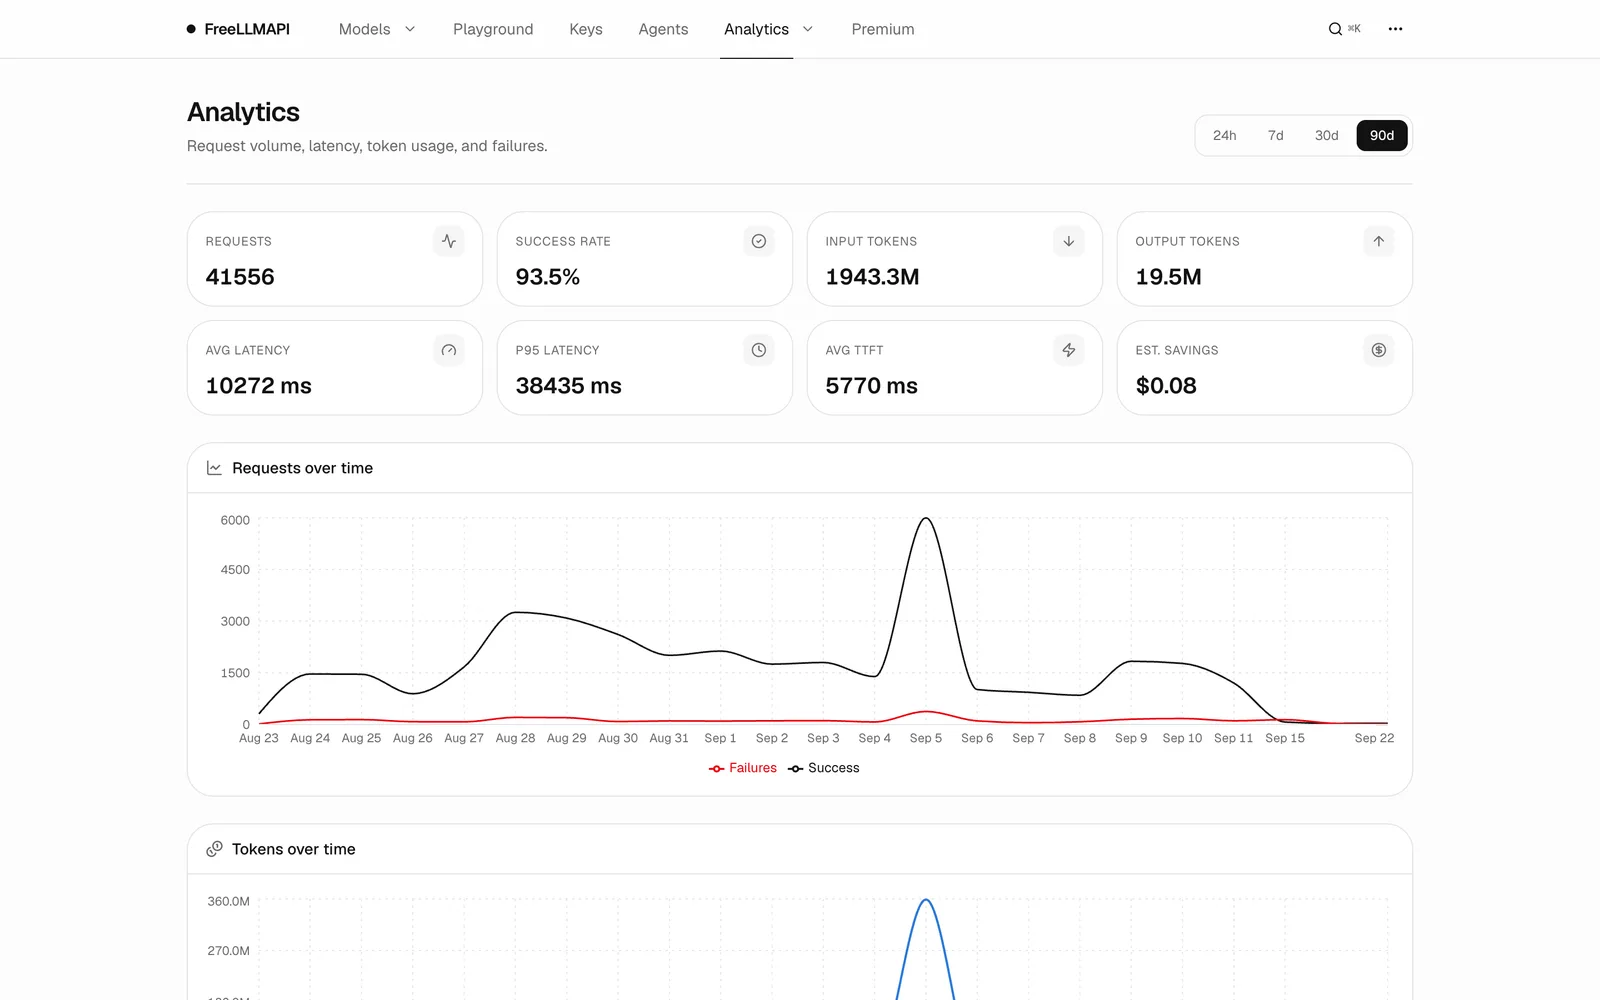
- 01 / 04
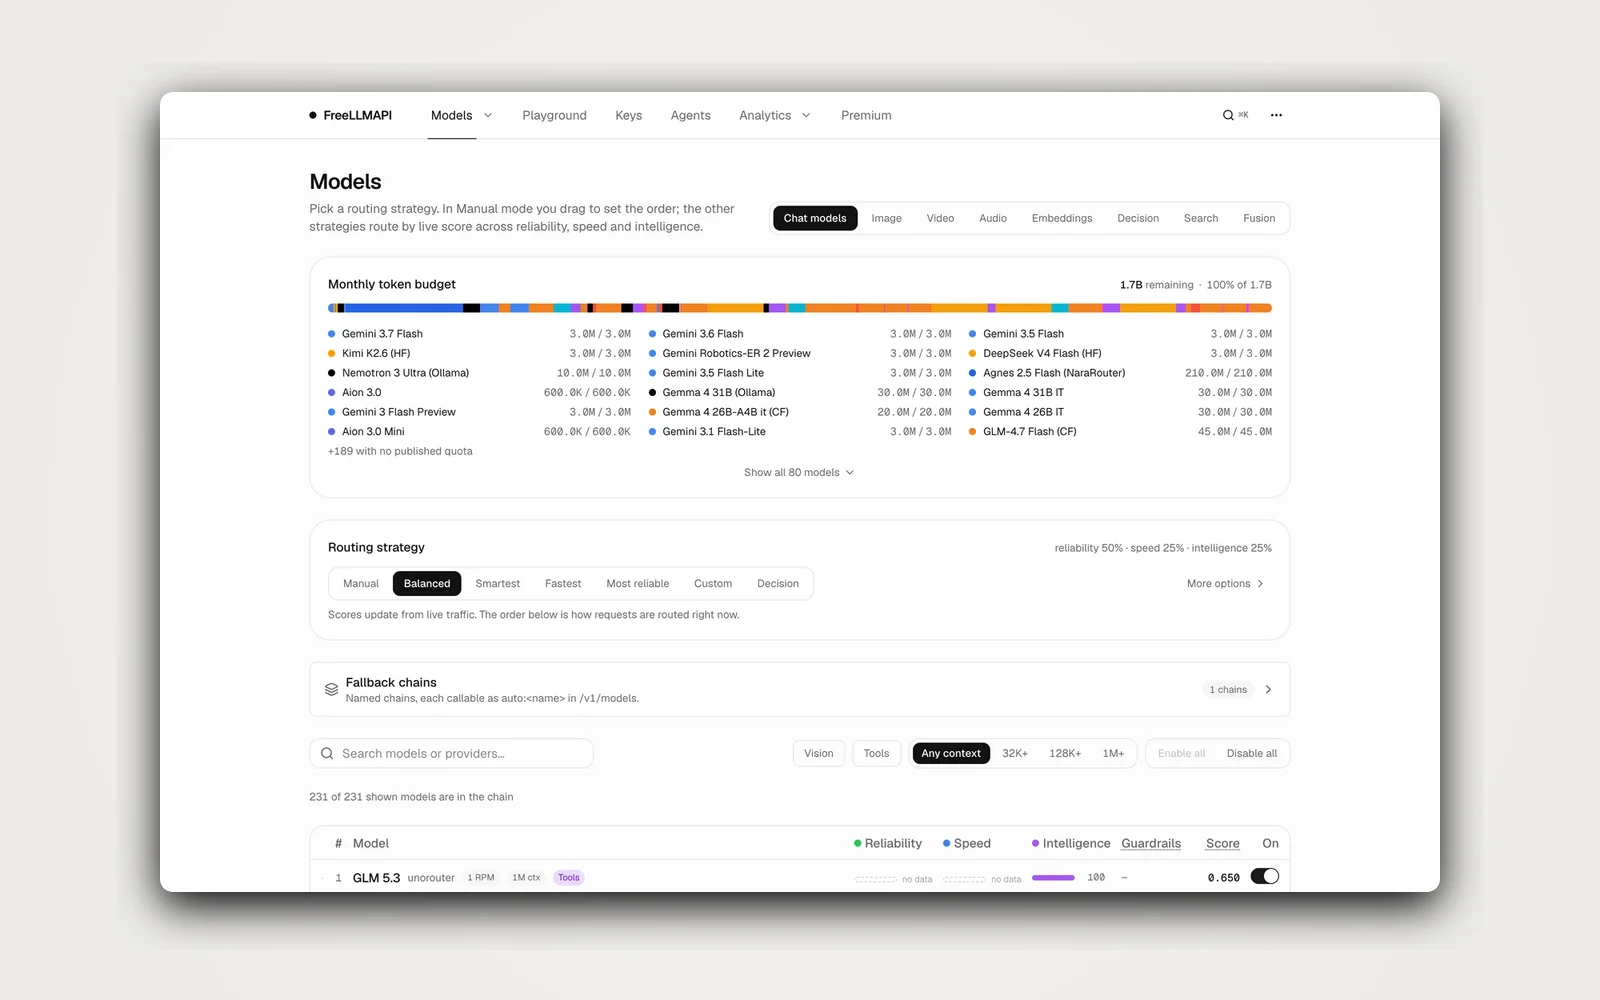
See your free capacity
The Models page starts with your monthly token budget: every connected provider’s free allowance, one segment per model.
- 02 / 04
Choose how requests are routed
Balanced, Smartest, Fastest, Most reliable or your own order. Each model is scored from live traffic.
- 03 / 04
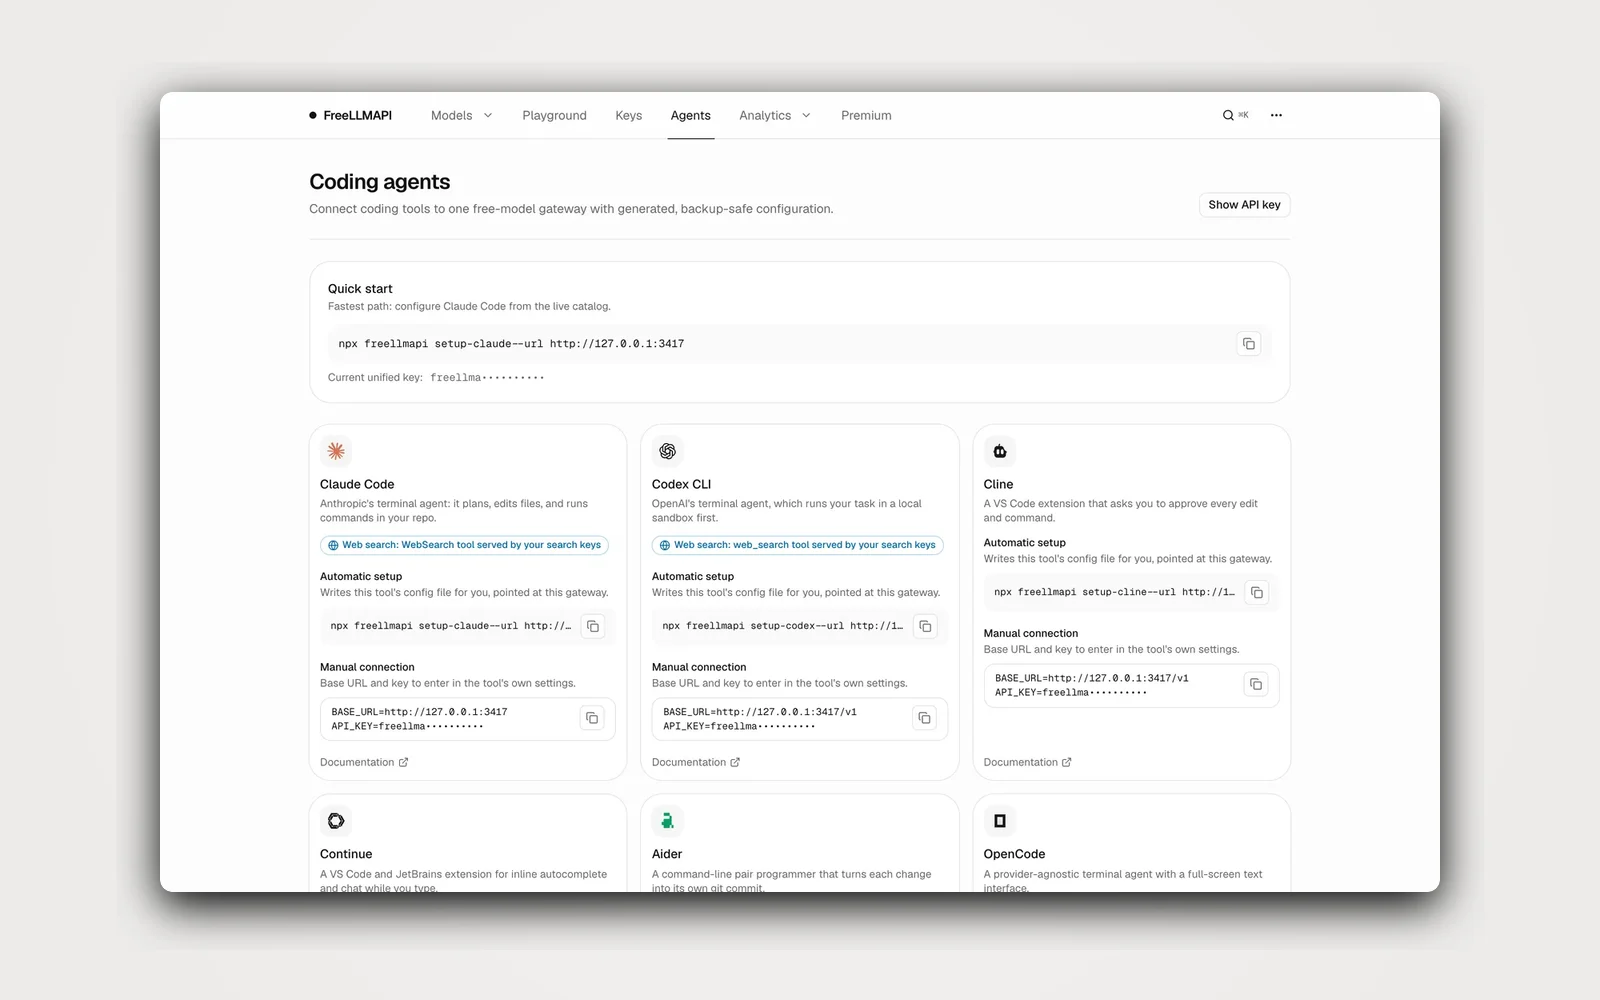
Connect your coding agents
One command writes the config for Claude Code, Codex CLI, Cline, Aider, OpenCode and more.
- 04 / 04
Watch your traffic
Requests, success rate, latency and token use, from the last 24 hours to 90 days.
The results
Free models
Providers in one pool
Free tokens each month
More work
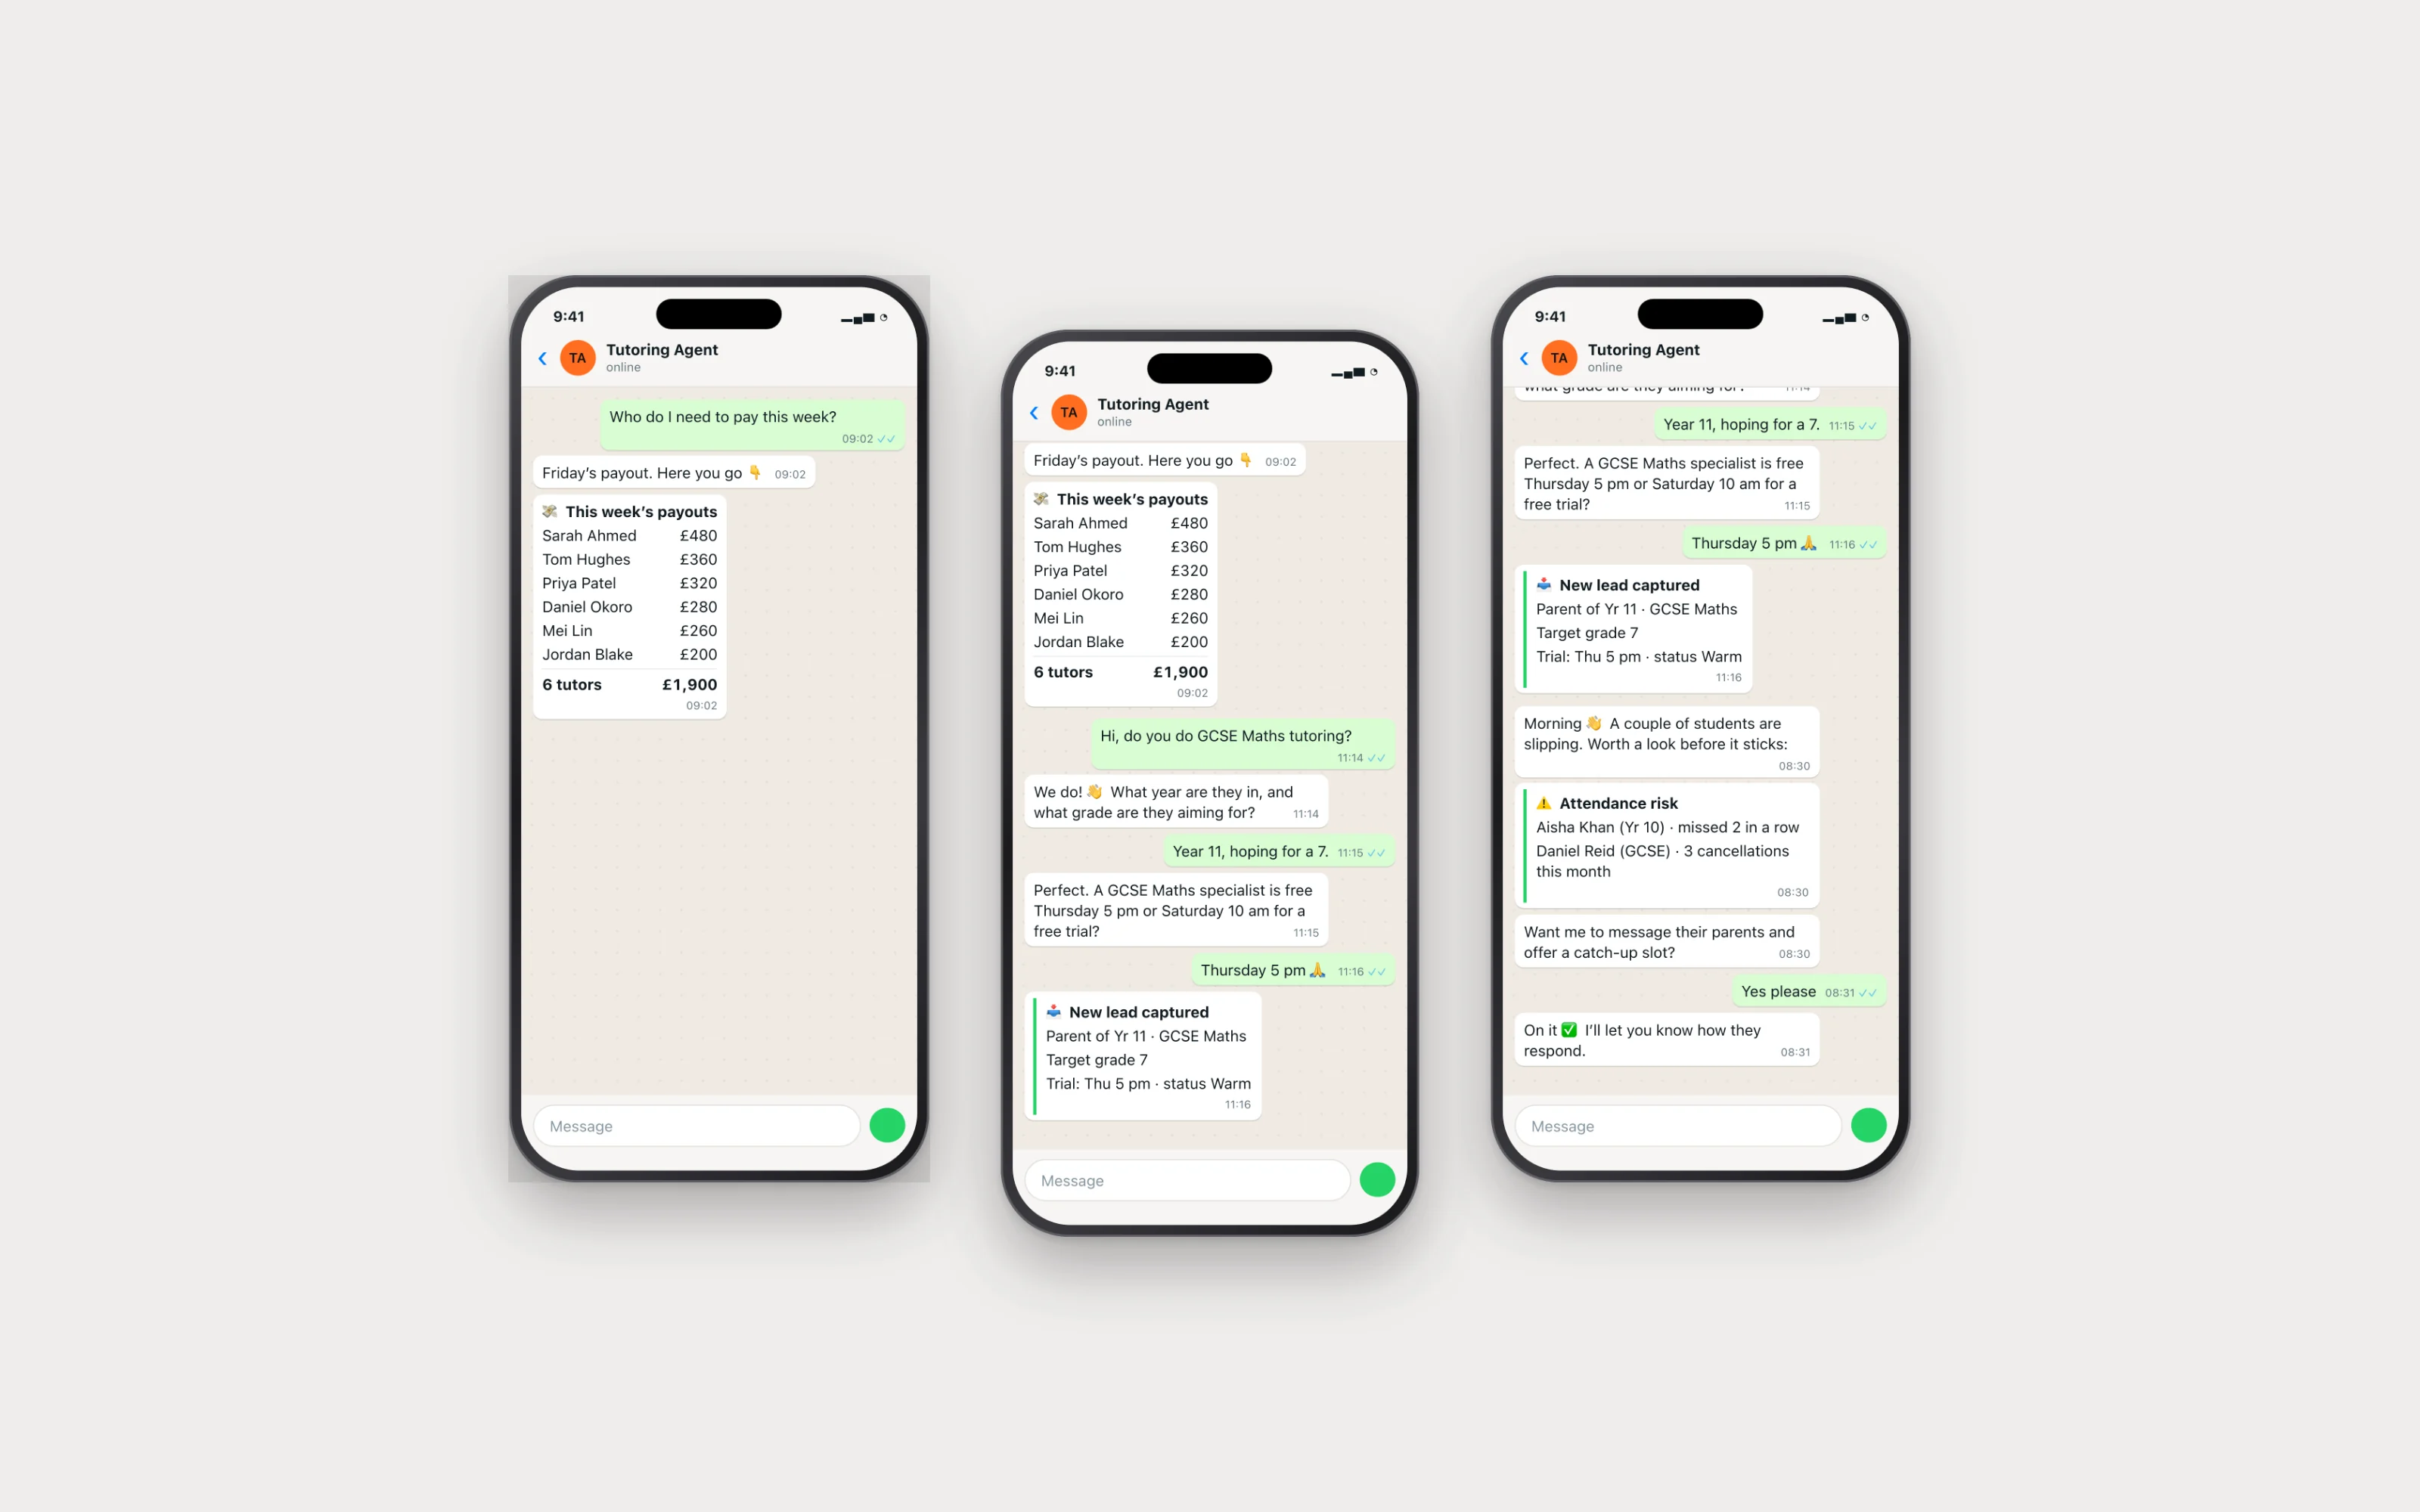 EducationTutor operations agent
The whole back office, on WhatsApp.
A single WhatsApp agent runs tutor check-ins, parent reports, and weekly payouts for a tutoring business.78%Admin hours savedRead the case study →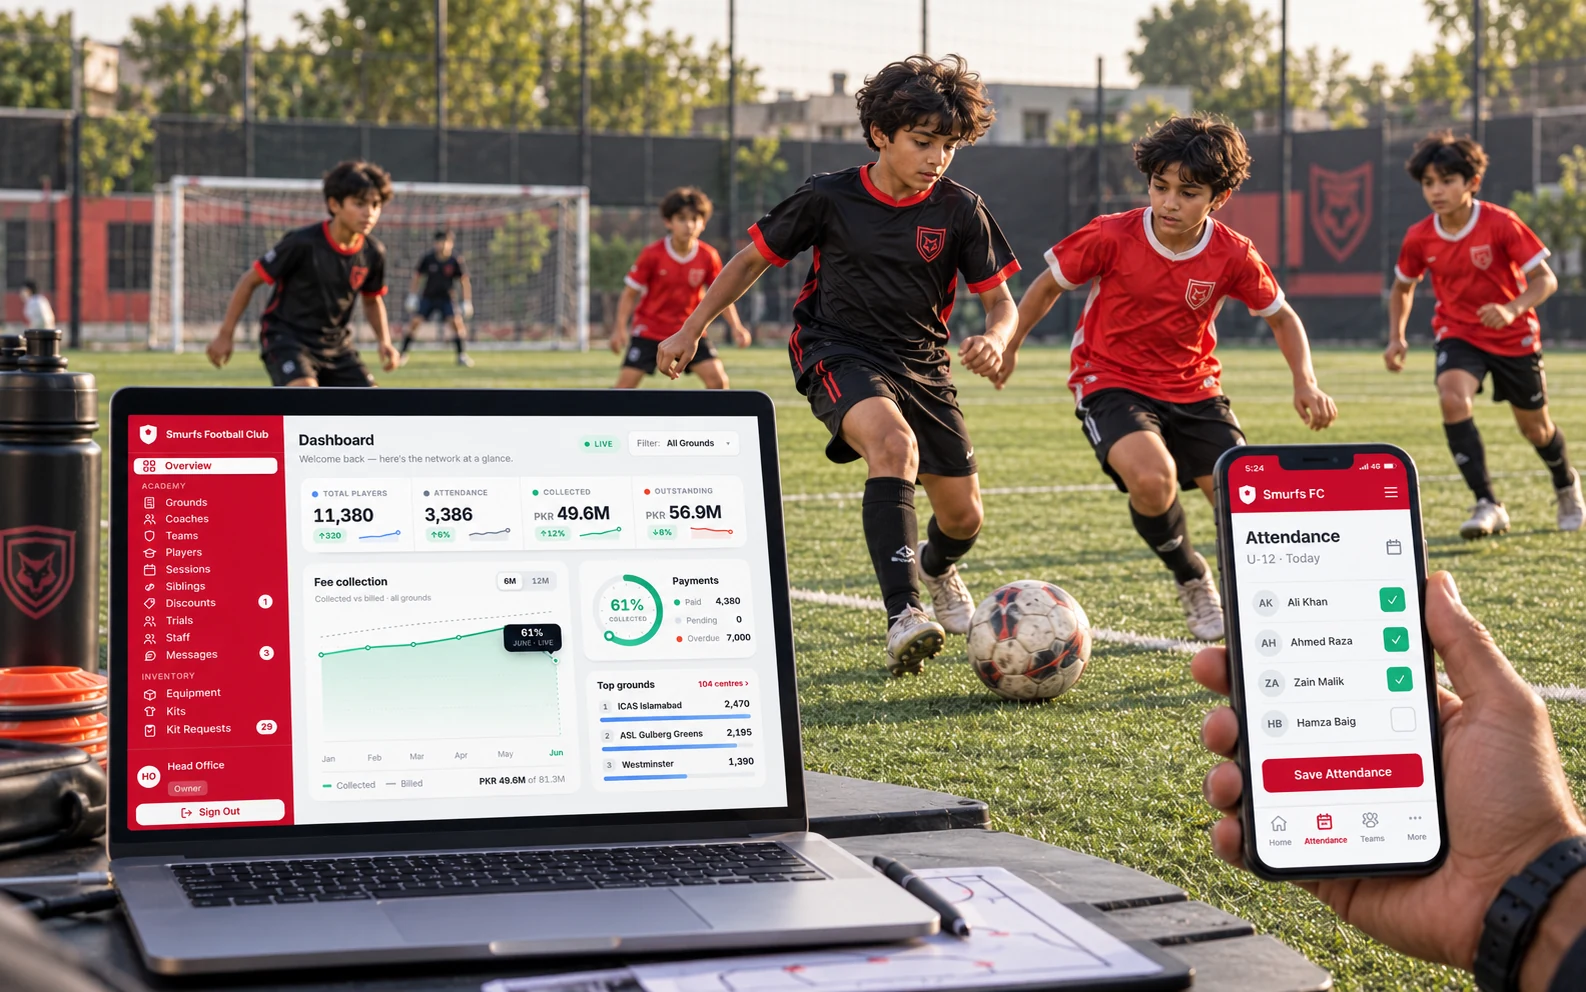 Sports · academy opsSmurfs FC · the academy OS
The academy OS for Pakistan’s largest club.
The back-office software for Pakistan’s largest football academy: enrolment, fees, comms, reports.95%+On-time fee recoveryRead the case study → Education · EdTechFind Tutor Web · the learning platform
A learning platform that wrote itself.
A full learning platform: 921 interactive lessons, live simulations, auto-marked mocks, and progress tracking across four exam boards, all written end to end by AI pipelines.921Interactive lessons liveRead the case study → Retail · convenienceSosho · autonomous social media
A social media manager that never clocks off.
An autonomous agent that plans, designs, posts, and replies to comments on Facebook and Instagram, built for convenience stores.24/7Hands-off social mediaRead the case study →